From Python + CUDA to Pure Rust + Metal 4: How zml-flow-rs Stops Us Writing a Kernel Per Model
Every image model I have ported in the last year arrived the same way: a PyTorch repository, a diffusers pipeline, some torch.compile, and a quiet assumption that you own an NVIDIA card. Sometimes there's a custom CUDA extension. Often there's flash-attn. The semantics that matter (which norm, which gate, where the modulation goes, where the tensors get rounded) live in Python code spread over a dozen files.
The way I ported those models to Apple Silicon was to rewrite them. ERNIE-Image-Turbo in Zig with hand-written Metal. Qwen-Image in Rust (qwen-image-rs). Krea-2 in Rust (zml-rs). MiniMax H3 in Rust. Each one got its own graph, its own tensor-name tables and its own fused kernels. Then came the slow part, autoresearch: qwen-image-rs reached its current speed through about 60 hand-run optimization commits, each hand-coding or hand-tuning something for exactly one architecture.
That doesn't scale. N models × M platforms × every custom kernel, written by hand, re-validated by hand.
zml-flow-rs is my attempt to stop doing that. It takes a model it has never seen, looks only at the safetensors headers, and derives the rest: the graph, the fusions, the precision formats, the schedule. It discovers the semantics the weights can't show from a single reference trace, runs the model on Metal 4 through a small model-neutral kernel vocabulary, synthesizes fused kernels from data instead of writing them, and compiles the whole pipeline into a standalone Rust executable.
Today it runs two architectures that share almost nothing, Qwen-Image-2.1 (a 32×4096 DiT) and Krea-2-Turbo (a 28×6144 GQA DiT with a separate text-fusion tower and a causal-3D VAE), end to end on an M5 Max, with no model name anywhere in the code. On Krea-2, the PNG it writes is pixel-for-pixel identical to the MLX reference.
This article covers how that works, what it actually removes from the porting job, and, honestly, what it doesn't.
Proof It Actually Works
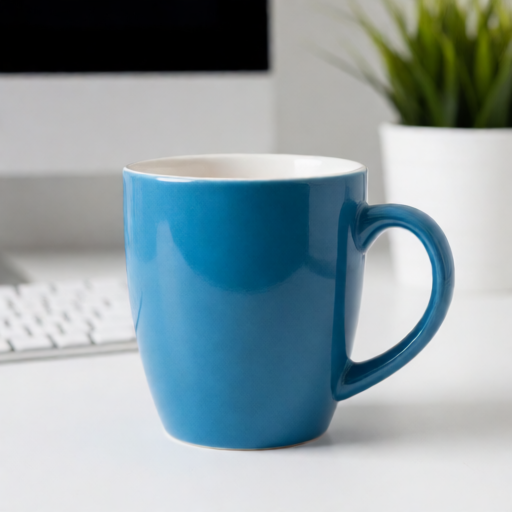
"A blue ceramic mug on a white desk." Krea-2-Turbo, 512², 8 steps, generated by the generic engine. Every one of the 786,432 RGB values equals the reference implementation's
rgb8output.
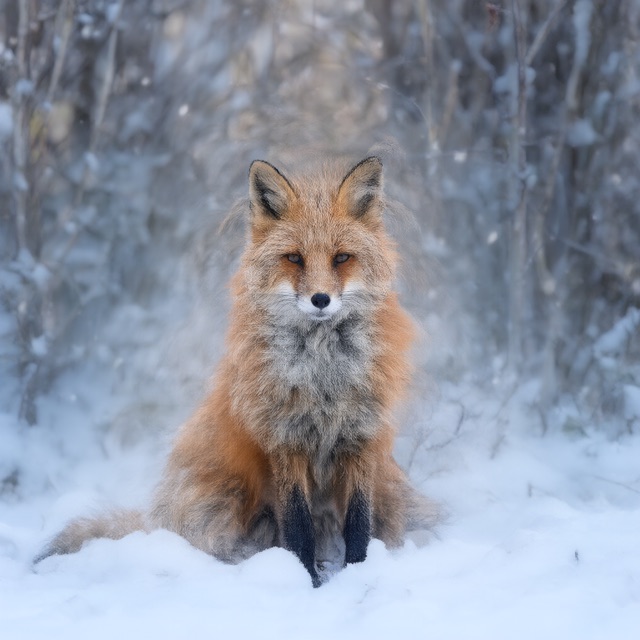
"A red fox sitting in a snowy forest at dawn, highly detailed". Qwen-Image-2.1, 1024², 8 steps, from the ahead-of-time compiled binary in 11.3 s. There's no interpreter, no genome inference and no Python in the process.
Both images come from the same engine. Neither model has a line of code written for it.
I – What a Python + CUDA Port Actually Costs
When a model lands as PyTorch + CUDA, "porting" to Metal actually means four separate jobs:
- Recover the graph. Read
transformer_*.py,attention_processor.py, the pipeline file and the scheduler, and write the forward pass again in the target language, with a table mapping every tensor name to its role. - Recover the semantics. The paper says "AdaLN". The code says
[shift, scale, gate]in some order,1 + scaleor not,tanhorsigmoidon the gate, interleaved or half-split RoPE,flip_sin_to_coson the timestep embedding. Get one wrong and the output is a plausible-looking wrong image. - Rewrite the kernels. A CUDA extension, a Triton kernel or
flash-attndoesn't port to Metal. You write MSL. Then you write the fused versions (SwiGLU GEMM, gated-residual GEMM, QKV + norm + RoPE) because the unfused chain is too slow. - Re-discover the optimizations. Which GEMMs are worth INT8, whether Q/K/V concatenation helps at this shape, which tile swizzle wins, what to overlap with what. On a new device, all of it again.
Jobs 1 and 2 are per model. Job 3 is per model × per platform. Job 4 is per model × per device. The Python reference isn't much help past job 1, because CUDA's kernels are not the ones you'll run.
zml-flow-rs goes after all four, and in each case the move is the same: replace code that encodes a decision with a search that finds it, and gate every result on measured evidence.
II – The Stack
weights on disk ──► zflow-genome ──► Graph (unrolled ops, blocks, edges)
  (headers only)       │ no model names, no per-architecture tables
                       ▼
                   zflow-fusion ──► candidates: sibling concat, epilogue,
                       │            elementwise chain, precision, tile, zero-copy
                       │   Proposed → CostModeled → Calibrated → EquivalenceGated → Accepted/Rejected
                       ▼
 device ─────────► zflow-calib ──► measured Metal kernels, fitted per class,
                       │            cached per exact device fingerprint
                       ▼
                   zflow-heft ───► HEFT scheduling: op level and pipeline level
                       ▼
 reference trace ─► zflow-exec ────► generic interpreter + semantics discovered from the trace
                       │            (CPU f32 reference, and zflow-exec-metal on the GPU)
                       ▼
                   zflow-codegen ─► record → emit straight-line Rust → standalone executable
Underneath sits Oak (oakoliver-ml-rs), the shared, model-neutral Rust foundation all my engines use: strict mmap-backed safetensors, checked tensor metadata, and oak-metal, a Metal 4 runtime with pinned bindings (live compiler, residency domains, argument tables, barrier-ordered command buffers, compiled against the Metal 4.1 toolchain). Oak provides the heavy, shared kernels: MLX-equivalent NAX BF16 GEMM and SDPA, MPP INT8 GEMMs, and the H256 Hadamard rotation.
Everything is Rust. The only Python left in the loop is the reference implementation, run once, to produce a trace. That is a big change in role: Python stops being the thing you translate and becomes the test oracle you check against.
III – Step 1: The Graph From Headers Alone
zflow-genome never reads a config file for architecture and never matches tensor names against a known list. It reads safetensors headers (names, shapes, dtypes) and infers the structure from topology, sizes and widths.
On Qwen-Image-2.1, this is what it recovered from structure alone:
- Towers and roles from boundary widths: a text LM (sequence), a vision tower (image input), the transformer (iterative denoiser), a VAE encoder (image input) and a VAE decoder (image output).
- Spatial compression 16 from the VAE's five resolution levels. The config's
scale_factor_spatialagrees, but it isn't used. - Vision patching of 256 pixels per token from the
[2,16,16]conv, with a 4-row merge (1152 → 4608). - Data flow: vision → LM → transformer ← VAE encoder (a
2·zmean/log-variance output), and transformer → VAE decoder, all inferred from widths. - The DiT genome: 32 blocks with Q/K/V siblings, a gated MLP (
4096 → 12288×2 → 4096), modulation, and 32×128 attention.
The same binary, with no code changes, also planned Krea-2-Turbo (28×6144, 48 heads over 12 KV heads, GLU 16384, a separate text-fusion refiner), Bonsai-8B (a 1-bit MLX LLM whose logical shapes it recovered from U32 packing), and Qwen3-0.6B.
The genome isn't perfect, and the next step is where its mistakes get caught.
IV – Step 2: Semantics From a Trace, Not From Code
Weights fix the math of every linear. They can't tell you whether a gate is tanh or sigmoid, whether RoPE is interleaved, what order the modulation chunks come in, or whether text rows go before image rows in the joint sequence.
The usual answer is to read the Python and hard-code it. zml-flow-rs searches for it instead. The reference is run once and its intermediate tensors are captured. A staged coordinate search then picks, for each unknown factor, the variant that reproduces the captured tensors. For Qwen-Image-2.1, the margin by which each winner beat the runner-up:
| factor | discovered | winner vs runner-up |
|---|---|---|
| gate function | tanh |
×169 |
| RoPE layout | interleaved | ×84 |
| modulation | [scale, gate], 1 + scale, no shift |
×1,150 |
| timestep sinusoid | flip_sin_to_cos |
×1,860 |
| joint sequence order | text rows first | ×18,834 |
| tail conditioning projection | (the genome had misread it) | ×2,486 |
| Euler sign | +1 | ×217 |
The search also reports factors that turned out not to matter, for example q/k norm kind at ×1.4. It doesn't invent certainty it doesn't have.
On Krea-2, the same search corrected the genome: a norm swap (×218), a missing rotary step, a missing GELU, the tail wiring, and a bogus fourth VAE upsampling level. Those fixes landed as generic rules in the genome and the image program, not as Krea patches, and Qwen's program stayed byte-for-byte unchanged.
This is the core of what changes when you port from Python. You don't read the reference to port it. You run it once and let it vote.
V – Step 3: Rounding Points Are Semantics Too
Getting the math right gets you close. On Krea-2 the first end-to-end result was a correct scene at 27.8 dB from the reference, with drift in the keyboard at the lower left. The op math was right. What was missing was where the reference rounds.
MLX (Krea-2's reference runs on MLX 0.32) casts the whole model to BF16, including norm scales and modulation tables. Every primitive of (1 + s) * norm(x) + b rounds to BF16. SiLU uses the fast exp, while the sigmoid gate uses the precise one. RoPE tables are built in F32 on the GPU. One-row linears go through a GEMV that rounds before the bias. K/V and output projections go through split-K.
None of that is visible in the weights, and most of it is barely visible in the Python. So precision became another searched dimension, scored by the fraction of BF16-exact outputs:
| stage | method | result |
|---|---|---|
| conditioning chain | exhaustive, 96 configurations | exact |
| block 0 | coordinate descent over 23 captured boundaries | all 22 node boundaries exact |
| denoiser output | coordinate pass over all 18 factors | exact; every factor decisive at ×5e8–8e8 |
| flow update | coordinate | exact (euler = primitive) |
The text conditioner and the VAE got the same treatment. The VAE turned out to route its 3×3 upsampler convs through Winograd F(6×6, 3×3) with a NAX F32 batched GEMM, because on an M5 Max MLX runs every F32 matmul on NAX by default. That's not the kind of thing you find by reading a paper.
The result: prompt → final latent → decoded RGB → PNG, bit-identical to the MLX reference. Every one of the 786,432 RGB values matches, on the canonical 512² request and on held-out prompts at 768² and 1024². Nothing in the precision vocabulary names a model. The defaults keep the old behaviour, and Qwen's path doesn't use any of it.
VI – Step 4: No Kernel Per Model
This is the part that answers "do I still have to write custom kernels?"
A small, model-neutral vocabulary
The executor is a generic interpreter over one trait. This is the whole contract a backend has to satisfy:
pub trait Backend {
    type T;
    fn upload(&mut self, data: &[f32], rows: usize, cols: usize) -> anyhow::Result<Self::T>;
    fn download(&mut self, t: &Self::T) -> anyhow::Result<Vec<f32>>;
    fn weight(&mut self, w: &WeightRef) -> anyhow::Result<Self::T>;
    fn linear(&mut self, x: &Self::T, w: &Self::T, b: Option<&Self::T>) -> anyhow::Result<Self::T>;
    fn norm(&mut self, x: &Self::T, gamma: Option<&Self::T>, beta: Option<&Self::T>, sem: NormSem, group: usize) -> anyhow::Result<Self::T>;
    fn modulate(&mut self, x: &Self::T, shift: &Self::T, scale: &Self::T, plus_one: bool, row_select: Option<&[u32]>) -> anyhow::Result<Self::T>;
    fn rope(&mut self, x: &Self::T, cos: &Self::T, sin: &Self::T, head_dim: usize, layout: RopeLayout) -> anyhow::Result<Self::T>;
    fn attention(&mut self, q: &Self::T, k: &Self::T, v: &Self::T, heads: usize, kv_heads: usize, head_dim: usize, mask: AttnMask, prefix_rows: usize) -> anyhow::Result<Self::T>;
    fn act(&mut self, x: &Self::T, f: ActFn) -> anyhow::Result<Self::T>;
    fn glu(&mut self, gate: &Self::T, value: &Self::T, f: ActFn) -> anyhow::Result<Self::T>;
    fn gated_residual(&mut self, x: &Self::T, y: &Self::T, gate: &Self::T, g: GateFn, row_select: Option<&[u32]>) -> anyhow::Result<Self::T>;
    // ... add, slices, concat, sync, plus defaulted extensions
}
Every model is expressed in these ops. Kernels are written per op class, once, not per model. The variation between architectures (tanh vs sigmoid, interleaved vs halves, 1 + γ or not) is a parameter, not a new kernel.
Newer capabilities (quantized linears, fused norm-modulate, exact-precision lowerings) are defaulted trait methods. The default is a host reference or the unfused composition, and Metal overrides it. That means the CPU reference, the Metal backend and the AOT recorder all keep working as the vocabulary grows.
Here's the tally of MSL the engine owns for two complete, very different architectures (text encoders, DiTs, VAEs, both precision regimes):
| file | lines | what it is |
|---|---|---|
kernels.metal |
287 | norms, modulate, RoPE, activations, gates, elementwise |
numerics.metal |
328 | the primitive BF16-lattice lowerings (the exact-precision path) |
fused.metal |
175 | norm + modulate, head norm + RoPE |
image_exact.metal |
567 | F32 implicit-GEMM conv in MLX's MMA order, Winograd transforms, exact softmax |
That's about 1,350 lines, shared by every model. The GEMMs and attention come from Oak's pinned kernels (and a vendored copy of MLX v0.32's MIT NAX GEMM template instantiated for F32), and those are model-neutral too.
Fused kernels as data: zflow-synth
The fused kernels were the last place where hand-writing crept back in. Oak had a hand-written SwiGLU GEMM, a gated-residual GEMM and a QKV GEMM, each with its math fixed: SiLU only, no biases, F32-prepared gates. A GELU-tanh GLU, a BF16-lattice SiLU, a bias or a sigmoid gate meant falling back to unfused ops, or writing another kernel.
zflow-synth turns an epilogue into data: a GEMM (or two sharing an input, for a GLU) followed by a list of the backend's own pointwise ops.
pub enum Step {
    Act(ActFn),
    Glu { f: ActFn, gate_first: bool },
    Add { operand: usize },
    GateMul { g: GateFn, operand: usize, v_is_gate: bool },
    GatedResidual { g: GateFn, other: usize, v_is_branch: bool, gate: usize, sel: Option<usize> },
    Modulate { shift: usize, scale: usize, plus_one: bool, sel: Option<usize> },
}
The same description has two readings:
- unfused: the steps are backend calls, in order. This is the reference.
- fused:
msl::emitwrites one Metal kernel, MLX's NAX tile loop (64×128×256 tiles, 2×4 simdgroups, the same route Oak's regular GEMM plan uses) with the steps evaluated per output element while the accumulator is still in registers.
The pointwise math in the emitted kernel is extracted verbatim, at compile time, from the engine's own kernels.metal and numerics.metal via include_str!, and a test checks it. So the fused and unfused paths can't drift apart, and the fused kernel rounds to BF16 exactly where the unfused chain would have stored a BF16 tensor. Nothing names a model: a region qualifies by the ops it contains. ZFLOW_SYNTH=0 forces the unfused route for A/B runs.
Measured on the M5 Max:
- Kernel level: 20 cases on random operands, including patterns that never had a hand-written kernel (bias + GELU, a plain residual add, a sigmoid output gate, and a three-step GELU → modulate(1+γ) → gated-residual chain). Every output value is bit-identical to the unfused ops. The synthesized kernel takes 0.88–1.05× the unfused time and is on par with Oak's hand-written kernels where those apply.
- Krea-2, end to end: 56 gated residuals (an F32 residual that Oak's kernel couldn't take, so it was never fused before) and 28 SwiGLUs each become one kernel. GPU time per step drops 700 → 648 ms (−7.4 %), dispatches drop 842 → 730, and the PNG is byte-identical, still bit-exact to the reference.
- Qwen-Image, end to end: GEMM-bound at 4,112 rows, so fusion gives no measurable gain over unfused. But the synthesized kernels are 5–9 % faster than Oak's hand-written ones and, unlike them, exact: Oak's route changes the image's bytes (48.7 dB), synth's doesn't.
On Qwen, the generated kernels beat the hand-written ones on both speed and exactness. On Krea, they fused patterns the hand-written ones couldn't take at all.
This is the direct answer to "I have to write a custom fused kernel for this model's weird gate." You don't. The fusion pass finds the region, the synthesizer writes the kernel, and the equivalence gate decides whether to keep it.
Every fusion has to earn its place
A fusion that's faster but changes the math isn't accepted by default. zflow-fusion moves each candidate through phases: Proposed → CostModeled → Calibrated → EquivalenceGated → Accepted | Rejected. The equivalence gate compares every fused group with its unfused chain on the same operands, over all groups of a real forward pass, at rel-RMS ≤ 2e-3. It also rejects a kind that's clearly slower (> 3 %).
The gate earns its keep. Oak's hand-written fused GEMMs are faster on Krea but slower on Qwen at Qwen's shapes (SwiGLU 456 ms vs about 421 ms for the tuned regular route, gated residual 357 vs about 287 ms). The gate rejected them on Qwen and accepted them on Krea. Nobody had to know that ahead of time.
VII – Step 5: Precision Formats Derived, Not Picked
INT8 is the biggest speed lever and the easiest way to wreck image quality. zflow-format doesn't pick from a menu. It treats the numeric format as a property of every graph edge and conversions as graph nodes, then enumerates weight format × activation format × rotation × placement under four algebraic rules. The main one is rotation invariance: (x·H)(Hᵀ·W)ᵀ = x·Wᵀ for orthogonal H.
W8A8Rot, the format qwen-image-rs found by hand, isn't named anywhere in the code. It emerges as a legal point: I8 per-row + H256 on both sides. Every candidate is then gated on numerics measured from the real checkpoint and on the model's own image-level quality gate.
The outcomes differ by model, and that's the point:
- Qwen-Image-2.1:
uniform:w8a8rot-h256is chosen by--formats auto. Denoise drops from 10.9–11.9 s to 8.64–8.89 s (−20 %) at 45.2 dB against our own BF16, passing the 40 dB gate. - Krea-2-Turbo: every format fails the near-BF16 gate (PSNR ≥ 30 dB, SSIM ≥ 0.98, LPIPS ≤ 0.05), even INT8 on a single one of 224 linears. The same gate also fails
zml-rs's hand-tuned 4.85 s INT8 route. So the gated plan for Krea is BF16, because that's what the measurement says.
The search also proposed something qwen-image-rs never tried: block-64 weights × H256-rotated per-row activations. Both error sides fit their budgets. It first ended Rejected("no kernel"), and after one catalog entry (Oak's segmented g64 kernel with a broadcast per-row activation scale) it became executable. This is the first concrete lead the derived search has produced.
VIII – Step 6: Calibrate on the Device, Schedule With HEFT
The planner doesn't trust a theoretical roofline. zflow-calib measures the actual Metal kernels at the actual shapes, behind a guard that is paranoid on purpose:
- GPU idle ≤ 8 % and host load < 3 before each chunk;
- a contention check after it;
- a second measurement of every fresh entry, kept only within 7 % (otherwise the median of three);
- a canary BF16 4096³ GEMM before and after, anchored to the fastest reading seen.
The cache is keyed by an exact device and Oak-revision fingerprint. When Oak moved mid-session, the old cache was refused (fail closed), not silently reused.
zflow-heft then schedules at two levels: fused op groups on the GPU queue and CPU pool, and whole pipeline phases (load, prepare, execute) across I/O, CPU and GPU. It found on its own that the transformer weight load can overlap text encoding (0.39 s predicted, 0.25 ± 0.15 s in the ledger) and that the VAE load can hide behind denoising.
Is the planner right? A falsifiable scorecard
To keep myself honest, every decision qwen-image-rs reached by autoresearch went into a ledger: 73 entries, each citing its source commit, each labelled predictable_from_topology_and_calibration, needs_numerics_gate or out_of_scope. The probe gets only the weights and the device, and its plan is scored against the predictable entries only.
| calibration | predictable claims matched (tested) |
|---|---|
oak-metal 9ac656e, first clean run |
19 / 33 (58 %) |
oak-metal 9b80710, fully guarded |
15 / 33 (45 %) |
The second, stricter run scored lower, and I'm reporting that one. The claims that held in both runs are the robust ones: step and per-op time shares, precision ordering (including W8A8Rot beating BF16 at 4096³, 1,710 vs 2,176 µs), the long-K swizzle win, split-K rejection, and the INT8 resident-bytes saving (14.23 → 7.69 GB predicted, 13.3 → 7.7 GB measured). The ones that flipped (tile variants, Q/K/V concat) sit inside the replicate noise. Pipeline and memory decisions are weak (2 / 11) for reasons I understand: no memory cap wired into HEFT yet, and a warm-memcpy upload model where qwen-image-rs was page-fault bound.
It predicted a 1,148 ms DiT step for Qwen-Image at 1024². qwen-image-rs measures 1,227–1,253 ms. From weights alone, on first contact.
IX – Step 7: Compile It to a Standalone Binary
An interpreter is great for discovery and bad for shipping. zflow-compile runs each stage once on a recording backend, captures the straight-line op tape (shapes, weight references, constants) and emits a standalone Rust crate:
- a
WEIGHTStable of file offsets, mapped zero-copy at runtime; - one straight-line function per stage, freeing each temporary after its last use;
- constants via
include_bytes!; - weight-only work (VAE kernel collapse, INT8 preparation, BF16 casts) hoisted to load time.
The binary links only the Metal backend, host helpers and the tokenizer. nm shows zero interpreter and genome symbols, against 18 and 47 in the interpreted example.
| Qwen-Image-2.1 (1024², 8 steps) | Krea-2-Turbo (512², 8 steps) | |
|---|---|---|
| generated code | 303 KB, 1,517 ops | 333 KB, ~1,700 ops |
| host issue per step | 4.8 ms → 0.5 ms | 0.24 ms |
| output vs interpreter | bit-identical | bit-identical |
| prompt handling | recompile per prompt length (~8 s) | any prompt, one binary |
The "any prompt" column needed the most work. Krea pads prompts to 546 ids, but the exact engine keeps only the key blocks that contain valid rows, so the tape changes with prompt length. zflow_codegen::param records the pipeline at several prompt lengths and unifies the tapes: ops must match one for one, and every differing integer must be affine in a small set of request integers (valid ids, LM rows, conditioning rows), fitted on two recordings and verified on the rest. The executable computes those integers from the prompt and dispatches exactly the interpreter's calls. It serves any prompt from 40 to 545 ids, bit-identical to the interpreter, and a prompt it can't serve is refused with a clear message instead of producing garbage.
X – Cross-Platform: What's Real and What Isn't
This is the part people ask about most, so here is exactly where it stands.
Only Apple Silicon Metal is real today. No CUDA or DirectML backend exists yet. What exists is an architecture where the platform is confined to two narrow seams:
pub enum ResourceKind {
    /// One Metal command queue (or CUDA stream / D3D12 queue elsewhere).
    GpuQueue,
    /// Host worker pool (page faults, dequant, tokenization, ...).
    CpuPool,
    /// Storage -> memory (page-in / mmap residency wiring).
    Io,
    Npu,
}

pub trait CostModel {
    /// Microseconds for `sig` on `resource`, or None when unsupported there.
    fn cost_us(&self, sig: &OpSignature, resource: ResourceKind) -> Option<f64>;
    fn transfer_us(&self, bytes: u64, from: ResourceKind, to: ResourceKind) -> f64;
}
…plus the Backend trait from section VI. The genome, the semantics artifacts, the fusion rules, the format algebra, HEFT and the codegen don't know what a Metal buffer is.
So porting to a new platform becomes a bounded, model-independent job: implement Backend (a couple of dozen ops, with defaults for the rest), expose its kernels to the calibrator, and teach zflow-synth to emit the new shading language. After that, every model the engine already runs comes along. The semantics discovered once from the Python trace are portable JSON. The fusion and format decisions are re-derived by measurement on the new device, which is exactly what should happen, because the right INT8 choice on an M5 Max is not the right one on an RTX card.
Compare that with the per-model port: a new platform means rewriting each model's kernels and re-running each model's autoresearch.
One more piece of evidence that this generalizes: the CPU f32 reference backend implements the same trait and runs the same graphs. Qwen-Image block 0 is at 3.37e-3 rel-RMS on CPU and 3.24e-3 on Metal, and the CPU residual equals the measured BF16-vs-F32 gap. It's not a second GPU platform, but it proves the interpreter isn't secretly Metal-shaped.
I'll believe the cross-platform claim fully when a CUDA backend runs the same Krea binary. It's item 9 on the roadmap, not a shipped feature.
XI – The Numbers
All on an Apple M5 Max (40 GPU cores), macOS 27.0, on a machine often shared with other agents. Contaminated runs are excluded, not averaged in.
Qwen-Image-2.1, 1024², 8 steps
| engine | total | quality |
|---|---|---|
qwen-image-rs (hand-built, ~60 autoresearch commits) |
11.87 s | 46.2 dB vs PyTorch MPS reference |
| zml-flow-rs, BF16, interpreter | 11.6–12.0 s | 47.8 dB vs qwen-image-rs's image |
| zml-flow-rs, AOT binary | 11.7–11.9 s | bit-identical to interpreter |
zml-flow-rs, --formats auto (W8A8Rot, gated) |
denoise 8.64–8.89 s (−20 %) | 45.2 dB vs our BF16 (gate: 40 dB) |
Krea-2-Turbo, 512², 8 steps
| engine | denoise | quality |
|---|---|---|
zml-rs BF16 (hand-built) |
7.06 s | reference |
zml-rs INT8 convrot tuned-v2 |
4.85 s | fails the near-BF16 gate |
| zml-flow-rs BF16 + fusions | 4.71–4.73 s | 27.3–27.8 dB vs reference decode |
| zml-flow-rs exact precision, interpreter | 5.80–5.85 s (6.05–6.09 s total) | bit-identical PNG |
| zml-flow-rs exact precision, AOT | 5.78–6.01 s (6.01–6.25 s total) | bit-identical PNG |
The generic engine lands at the speed of the hand-built BF16 engines out of the gate. On Krea, the BF16 path beats the hand-built BF16 denoise by about a third (mostly from one fix, covered below). The exact mode costs roughly a second over the fast BF16 path (the two were measured on different days, under different host load). It exists because "bit-identical to the reference" is a property worth paying for when you're validating a port.
That fix is worth a moment. Profiling the Krea step showed 114 host syncs per step: every (1 + γ) norm downloaded its gamma, added 1 on the host and uploaded it again. That's 380 ms of a 961 ms step spent in round trips. Folding the offset into the norm kernel (a new defaulted norm_offset op) took Krea's BF16 denoise from 7.65 s to 4.6 s, with the same bits. The profiler, not intuition, found it, and because it's a generic op, every future model with that pattern gets it for free.
XII – Honest Accounting
What zml-flow-rs does not do yet:
- It needs one reference trace per model family. Semantics discovery is the executor's version of calibration needing a device. You run the Python reference once. You don't run it again, and you don't port it.
- Initial noise and the sigma schedule still come from the trace for Krea-2's request inputs.
- Only Metal is implemented. See section X.
- Kernels still exist and are still written by someone. The ~1,350 lines of engine MSL and Oak's GEMM/SDPA/INT8 kernels are hand-written. The difference is that they're written once per op class, not once per model, and fused variants are synthesized. A genuinely new algorithm (a packed INT1 GEMM for Bonsai, the block-64 × rotated-activation kernel) is still new kernel work, and the ledger labels those
out_of_scopeinstead of pretending otherwise. - The planner's pipeline decisions are weak (2 / 11 in the ledger), and the size-generic kernel-curve sweep is written and unit-tested but hasn't completed on the device: a 9-hour guarded run was blocked by another GPU client, and I stopped it rather than loosen the guard.
- The planner scores 45–58 % on predictable hand-found decisions, depending on how strictly the calibration is guarded. That's a lot for first contact, and it isn't 100 %.
What I set out to avoid, and have so far: architecture names or per-model tables in logic, theoretical numbers presented as measured, precision changes accepted without a numerics gate, silent fallbacks, and tolerances tuned to pass. The workspace has 162 passing tests. None of them stand in for a real-checkpoint milestone.
XIII – Prior Art, and Where This Sits
None of the individual ideas here is new, and it would be dishonest to present them that way.
- Keep a change only if the evidence says it helps. Jürgen Schmidhuber's success-story algorithm (1997) kept a learner's self-modifications only while they measurably paid off, and the Gödel Machine (2003) went further, demanding a proof before any self-rewrite. zml-flow-rs applies the empirical version of that rule to inference plans: every fusion, format and tile has to beat the baseline on the device and pass a numerics gate.
- Measure on the actual machine. FFTW and ATLAS did this for FFTs and BLAS in the late 1990s, picking kernel variants by timing them on the host.
zflow-calibis the same idea, with more paranoia about contention. - Separate what a computation does from how it's scheduled, then search the schedule. Halide, TVM/Ansor, XLA and Triton. Their schedule search goes much deeper inside kernels (loop tiling, vectorization) than zml-flow-rs does today, and they run on many backends.
- Rewrite the graph, but verify each rewrite. TASO searched for graph substitutions and checked their equivalence. The fusion equivalence gate is a sibling of that.
- Recover a program from examples of its behaviour. Discovering gates, RoPE layout and rounding points from a reference trace is program synthesis by example, applied to a model's semantics.
What I haven't seen combined before is the specific pipeline: a graph inferred from weight headers alone, with no config and no name tables; semantics voted on by a single reference trace; rounding placement searched until the output is bit-exact; and the plan scored publicly against a ledger of decisions humans found by hand. That's a narrow claim. It's also one I can defend with the numbers above.
XIV – Lessons for Anyone Porting From Python + CUDA
1. Treat the Python reference as an oracle, not as source code. Run it once, capture intermediate tensors at every boundary, and search for the semantics that reproduce them. "text rows first, ×18,834" is a stronger statement than anything you'll get from reading pipeline_*.py.
2. Rounding placement is part of the model. Two implementations with identical math diverge chaotically over 8 steps × 28 blocks. If you want bit-exactness, and you do for validation, search for where the reference rounds the same way you search for which gate it uses.
3. Write kernels per op class, and make fusions data. Once an epilogue is a list of Steps whose math is lifted verbatim from the unfused kernels, the fused path can't disagree with the reference path, and a new model's odd gate doesn't mean new MSL.
4. Gate everything on measurement. Fusions, formats, tiles. Oak's fused GEMMs are a win on Krea and a loss on Qwen. INT8 is a 20 % win on Qwen and a quality failure on Krea. Any hard-coded answer would have been wrong for one of them.
5. Keep the platform behind the narrowest seam you can. A Backend trait and a CostModel. Everything above them (the part that took the longest to get right) shouldn't know what GPU it's on.
XV – What's Next
In rough order of impact: a memory cap in pipeline HEFT, cold page-fault-bound upload calibration, multiple I/O channels, the block-64 × rotated-activation INT8 kernel the search proposed, an activation-capture pass so INT8 decisions beyond block 0 rest on real evidence, and then the one this article is really waiting for: a second backend behind the same Backend / CostModel seams, and the same Krea binary running on it.
The next article will be about that backend, or about why it was harder than the seams suggest. Either way, you'll get the numbers.
– Antonio